Extrafemi Research · Naija Eval
Naija Eval: N-ATLaS, tested in the open
Nigeria’s own language model, scored on Hausa, Igbo and Yoruba speech and translation against its Llama base and four hosted models.
Extrafemi LabsThe Extrafemi Group5 min read
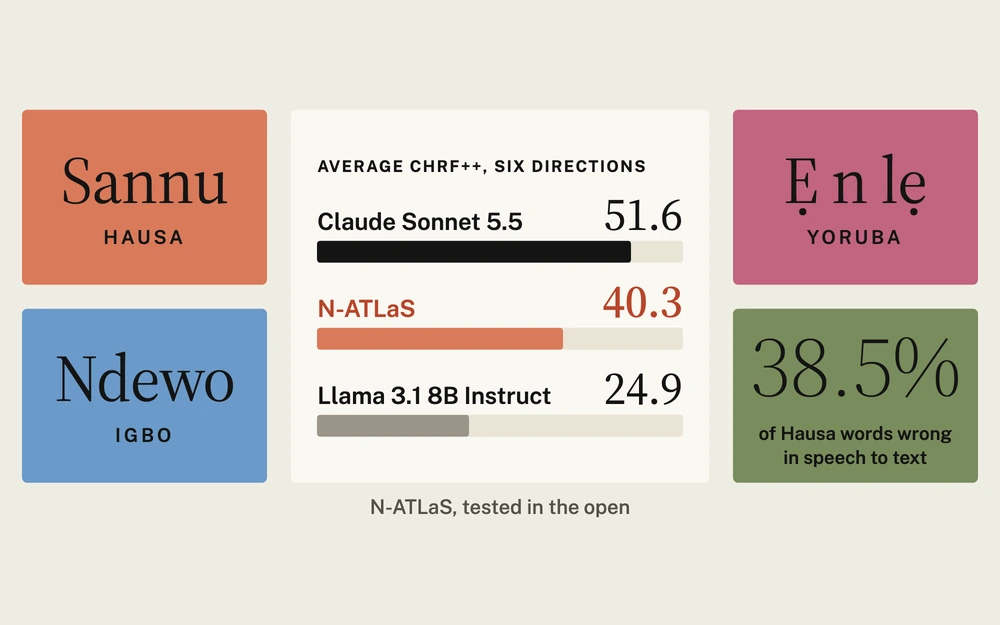
Naija Eval is Extrafemi's independent, reproducible scorecard for N-ATLaS, Nigeria's government-backed multilingual model (NCAIR / NITDA, powered by Awarri), on Hausa, Igbo and Yoruba. It is part of Extrafemi Research and an Extrafemi Labs build, and we are proud of it.
The N-ATLaS model card publishes only self-reported human ratings. We wanted numbers anyone can check, so we scored the model on public test sets, with one fixed prompt for every model, and published the method and the results in full.
This is what we tested, what we found, and what the numbers cannot tell you.
Why we tested it
A model is only as trustworthy as the evidence anyone else can check. For N-ATLaS, the published evidence is the model card’s own human ratings. That is a fair place to start, and a hard place to stop.
We wrote Naija Eval for four kinds of reader:
- Nigerian builders deciding whether to self-host N-ATLaS or pay for a hosted model.
- Policy makers and press, including NCAIR and NITDA, wanting an independent read.
- AI researchers checking method, sample sizes and reproducibility.
- Curious members of the public asking whether “our own AI” is any good.
How we tested
Everything runs on FLEURS, Google’s public test set of read speech, whose sentences are also aligned across languages as FLORES, which gives the translation tests. Both are CC BY-SA 4.0. The first pass was run on 8 October 2026.
- Speech
- NCAIR1’s Hausa, Igbo and Yoruba speech models (fine-tuned Whisper Small) against stock openai/whisper-small, greedy decoding. Scored by word error rate: the share of words the transcript gets wrong, so lower is better.
- Translation
- One fixed prompt for every model, temperature 0, first line of output kept. Scored with chrF++ from 0 to 100, where higher is better.
- Models
- N-ATLaS and its base, Llama 3.1 8B Instruct, ran locally in 4-bit on an Apple M5 with MLX. Claude Sonnet 5.5, Gemini 3.8 Flash, GPT-6.1 Sol and Claude Haiku 5.5 ran as hosted models through OpenRouter.
- Sample
- 100 items per language and direction. This is a first pass, not a leaderboard.
- Tone marks
- Both scores are also shown ignoring tone marks, so missing or wrong marks can be told apart from wrong words.
What we found in translation
Each model was scored in six directions: English to and from Hausa, Igbo and Yoruba. Averaged over the six, the hosted models lead, and N-ATLaS sits far above the Llama model it was built from.
Average chrF++ across six directions
Bars are drawn on a 0 to 60 scale.
N-ATLaS reaches 78% of the best hosted model’s translation score: 40.3 against 51.6, Claude Sonnet 5.5. Direction by direction, it looks like this:
| Direction | Llama 3.1 8B | N-ATLaS | Gain | Best hosted |
|---|---|---|---|---|
| English → Hausa | 22.7 | 47.4 | +24.7 | 51.7 |
| Hausa → English | 40.1 | 51.2 | +11.1 | 67.2 |
| English → Igbo | 17.0 | 37.1 | +20.1 | 43.9 |
| Igbo → English | 33.7 | 44.2 | +10.5 | 62.6 |
| English → Yoruba | 7.6 | 24.5 | +16.9 | 32.3 |
| Yoruba → English | 28.3 | 37.6 | +9.3 | 57.1 |
- The fine-tune is realN-ATLaS beats its Llama 3.1 base by 15.4 chrF++ on average. English to Yoruba goes from 7.6 to 24.5.
- HausaIt writes Hausa close to the best. English to Hausa scores 47.4, against 51.7 for the top hosted model.
- Into EnglishIt is weakest translating into English. Hausa to English scores 51.2 against 67.2; Yoruba to English 37.6 against 57.1.
- YorubaYoruba is hard for every model. No model passes 33 for English to Yoruba, and ignoring tone marks lifts N-ATLaS and each of the four hosted models by between 9.7 and 11.7 points.
- CostThe cheapest hosted model still wins on quality. Claude Haiku 5.5 beat N-ATLaS in all six directions; its 600 translations cost $0.03.
What we found in speech
Speech is where the Nigerian training shows most clearly. Stock Whisper Small has no Igbo at all, and the table below shows the share of words a transcript gets wrong.
Stock Whisper Small Hausa
92.1%
of words wrong
N-ATLaS Hausa speech model Hausa
38.5%
of words wrong
| Language | N-ATLaS | N-ATLaS, ignoring tone marks | Stock Whisper Small |
|---|---|---|---|
| Hausa | 38.5% | 38.5% | 92.1% |
| Igbo | 45.4% | 39.4% | no Igbo |
| Yoruba | 64.7% | 33.5% | 113.8% |
Above 100% means a model added more wrong words than the sentence had. Yoruba changes most with tone marks ignored: the N-ATLaS Yoruba model writes tone marks on some clips and drops them on others, so most of its errors as written are missing or wrong marks rather than wrong words.
Where N-ATLaS’s advantage lies
The hosted models score higher on translation. N-ATLaS’s advantage is where it runs: offline on a laptop or a server in Nigeria, with no text or audio leaving the machine.
One correction to the model card: N-ATLaS is built on Llama 3.1 8B (its config uses Llama 3.1’s rope scaling and 128k positions), not Llama 3.
What the numbers cannot tell you
We would rather state the limits than leave them to be found.
- Sample
- 100 items per language and direction. A first pass, not a leaderboard.
- Quantization
- The 4-bit local models may score a point or two below full precision.
- Contamination
- FLEURS and FLORES are public, so any model here may have seen them in training.
- Real speech
- FLEURS is clean read speech with formal vocabulary. Street voice notes will score differently.
Built to be re-run
The fixed prompt, the test sets and every step are set out on the Developers page, and the scripts and raw results are open on GitHub (opens in a new tab). A full run needs about 22 GB of downloads, an Apple Silicon machine for the local translation runs, and $1.59 in API costs for all four hosted models, 600 translations each. The speech test runs anywhere PyTorch does.
The results are also published as a model scorecard (JSON, opens in a new tab), a small shared format that Lodestone, Extrafemi’s library for reliable AI calls, can read to try the best-measured model first for a language.
N-ATLaS models are © Awarri Technologies and the Federal Government of Nigeria, under the N-ATLaS licence. FLEURS (Google) and FLORES (Meta and OLDI) are CC BY-SA 4.0. Naija Eval does not redistribute model weights.
Read the report
- The report, with every score and example translation: https://naija-eval.extrafemi.com (opens in a new tab)
- How we tested, and the limits: https://naija-eval.extrafemi.com/about (opens in a new tab)
- The code, with every script and the raw results: https://github.com/obasaolorunfemi-ai/naija-eval (opens in a new tab)
- The scores as data, in full and as a model scorecard: https://naija-eval.extrafemi.com/data/summary.json (JSON, opens in a new tab) and https://naija-eval.extrafemi.com/data/scorecard.json (JSON, opens in a new tab)
- How to re-run it: https://naija-eval.extrafemi.com/developers (opens in a new tab)
We built Naija Eval because Nigerian builders, policy makers and researchers deserve numbers they can check. We are proud to publish them.